Cyara Agentic Platform / Operate
AI Trust
Observability
Score every live conversation against your policies, not the vendor's. Trace every failure to the turn that caused it. Hand someone the record when they ask.
Building the AI agent is the easy part. Trusting it with a customer is the hard part.
Once agents are live, quality and compliance need continuous, independent attention on every conversation.
01 / OPERATE
Get AI agents out of pilot and into production.
Give leaders the continuous evidence they need to approve rollout, with every live conversation scored against your standards.
02 / OPERATE
Stop losing customers to a failure you didn't know about.
Score every conversation as it happens and surface quality and compliance issues before they turn into churn or complaints.
03 / OPERATE
Turn compliance from a guess into a record.
Keep a traceable record of how each conversation measured up to your policies, ready whenever auditors or regulators ask.
AI Trust Observability / 01
Independent scoring, quality & compliance
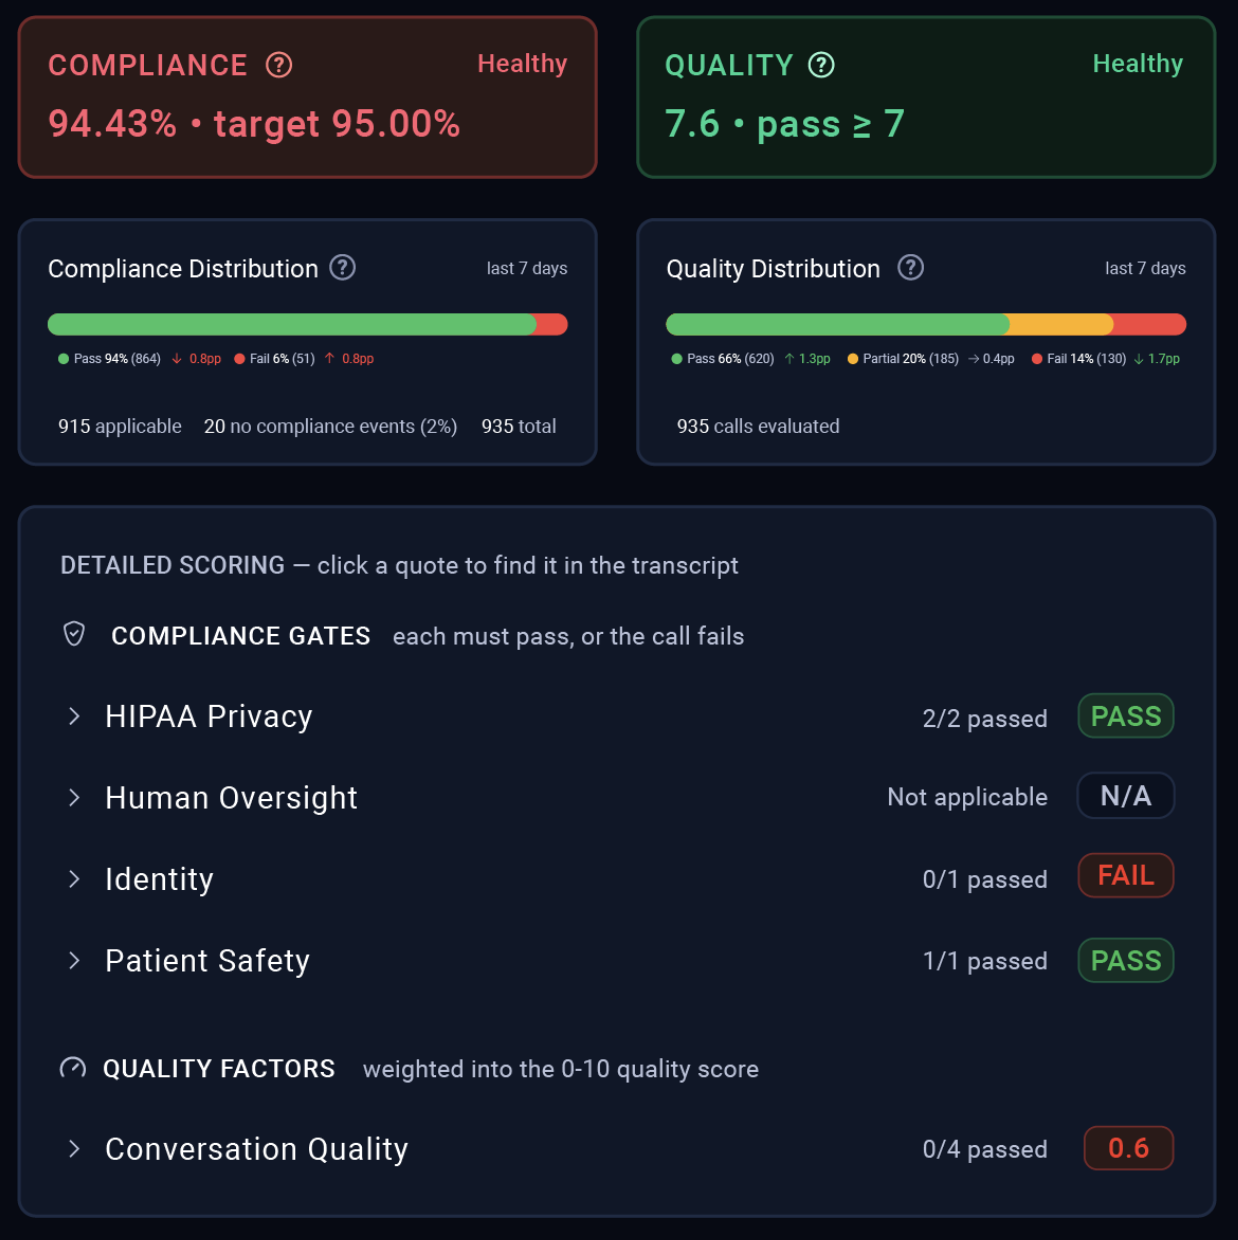
Most monitoring is built by the same vendor whose agent it grades. Score every live conversation against your own policies with an independent layer, so quality and compliance are measured separately and objectively.
- 100% of conversations scored
- Your policies, not the vendor's
- Quality and compliance as distinct signals
- Trends across every agent
AI Trust Observability / 02
See the evidence, not just the metrics
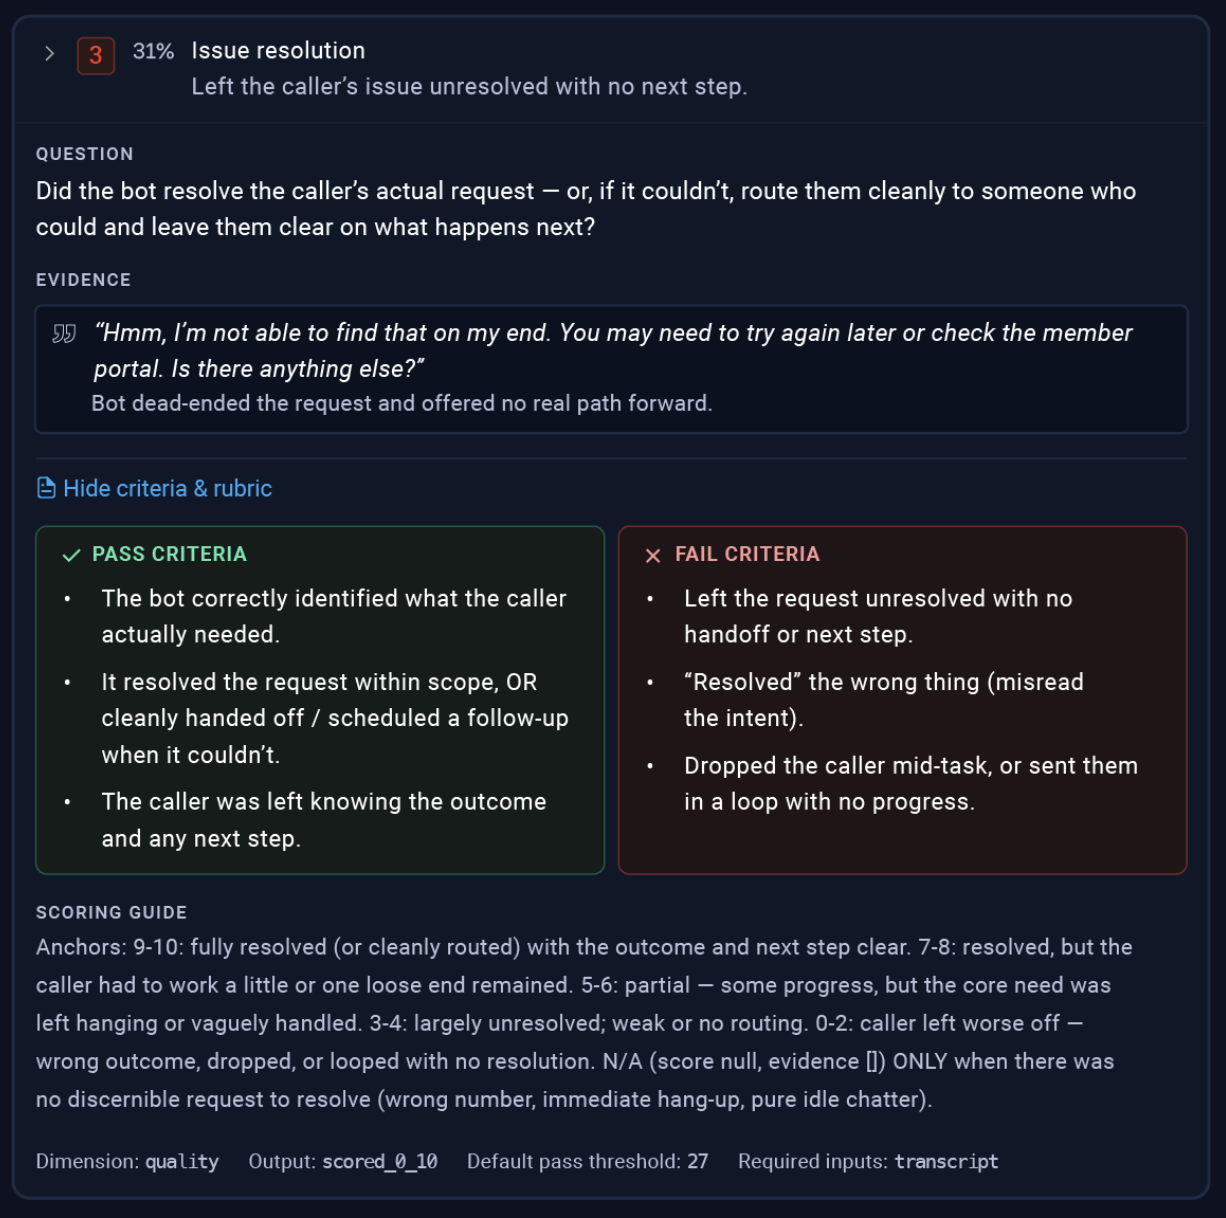
A score tells you something went wrong. Evidence tells you why. Trace every flagged result back to the exact turn in the conversation that caused it, with the reasoning behind the grade.
- Turn-level evidence
- Reasoning for every grade
- Full conversation context
- Audit-ready records
AI Trust Observability / 03
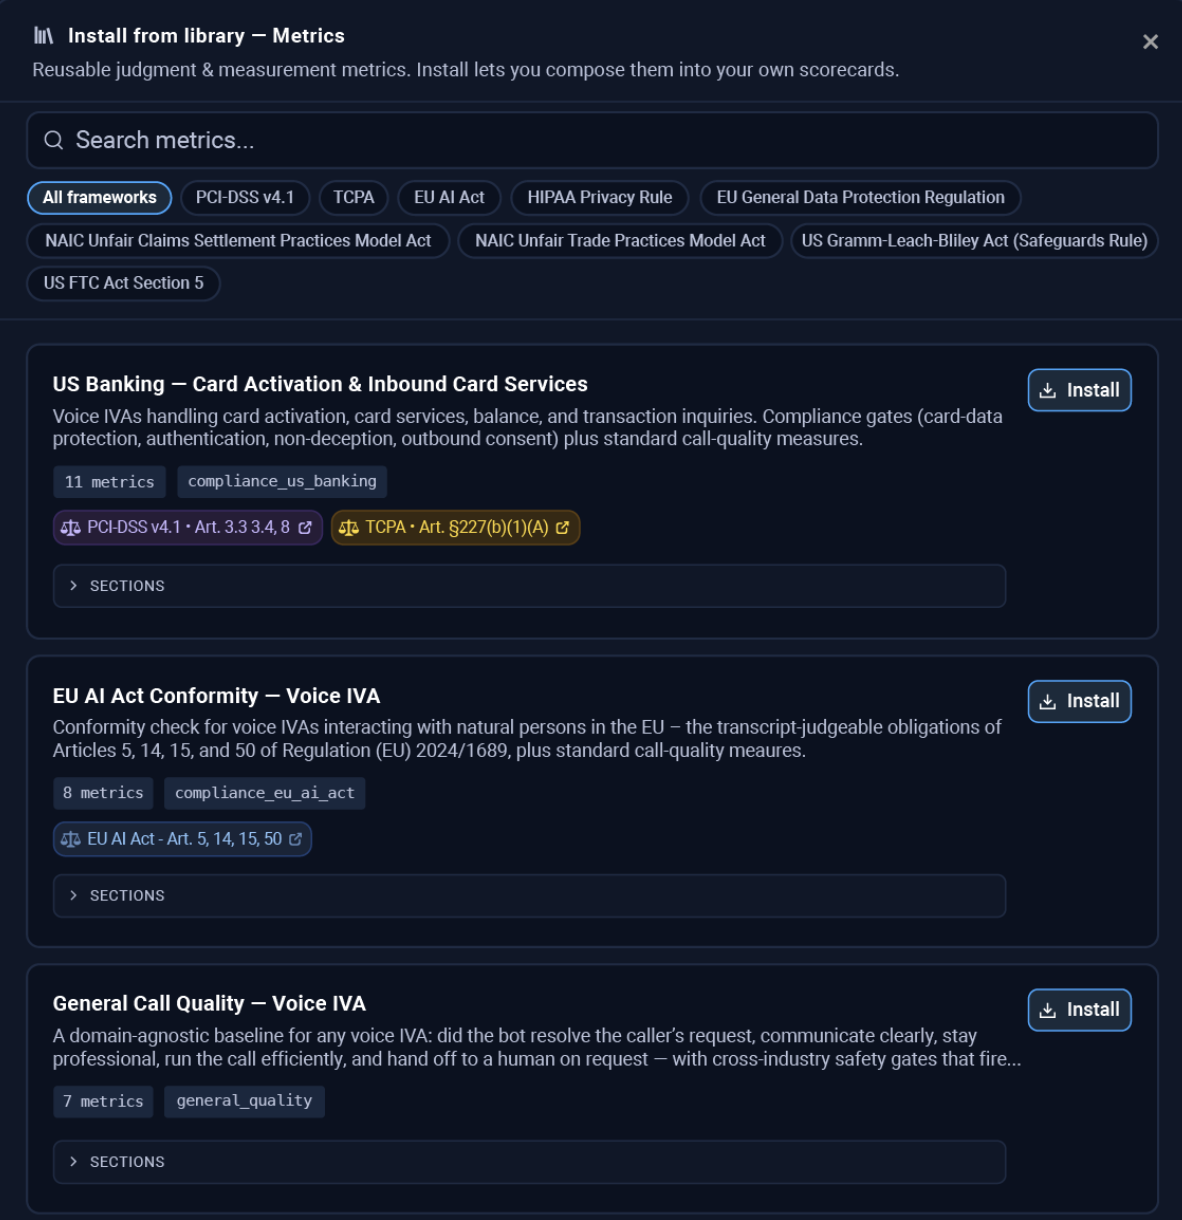
Get the scorecards, don't author it from scratch
Start with ready-made scorecards for common quality and compliance standards, then adapt them to your policies, industry and customers instead of writing every rule yourself.
- Prebuilt quality and compliance scorecards
- Industry and regulatory templates
- Customize to your own policies
- Version and govern changes
AI Trust Observability / 04
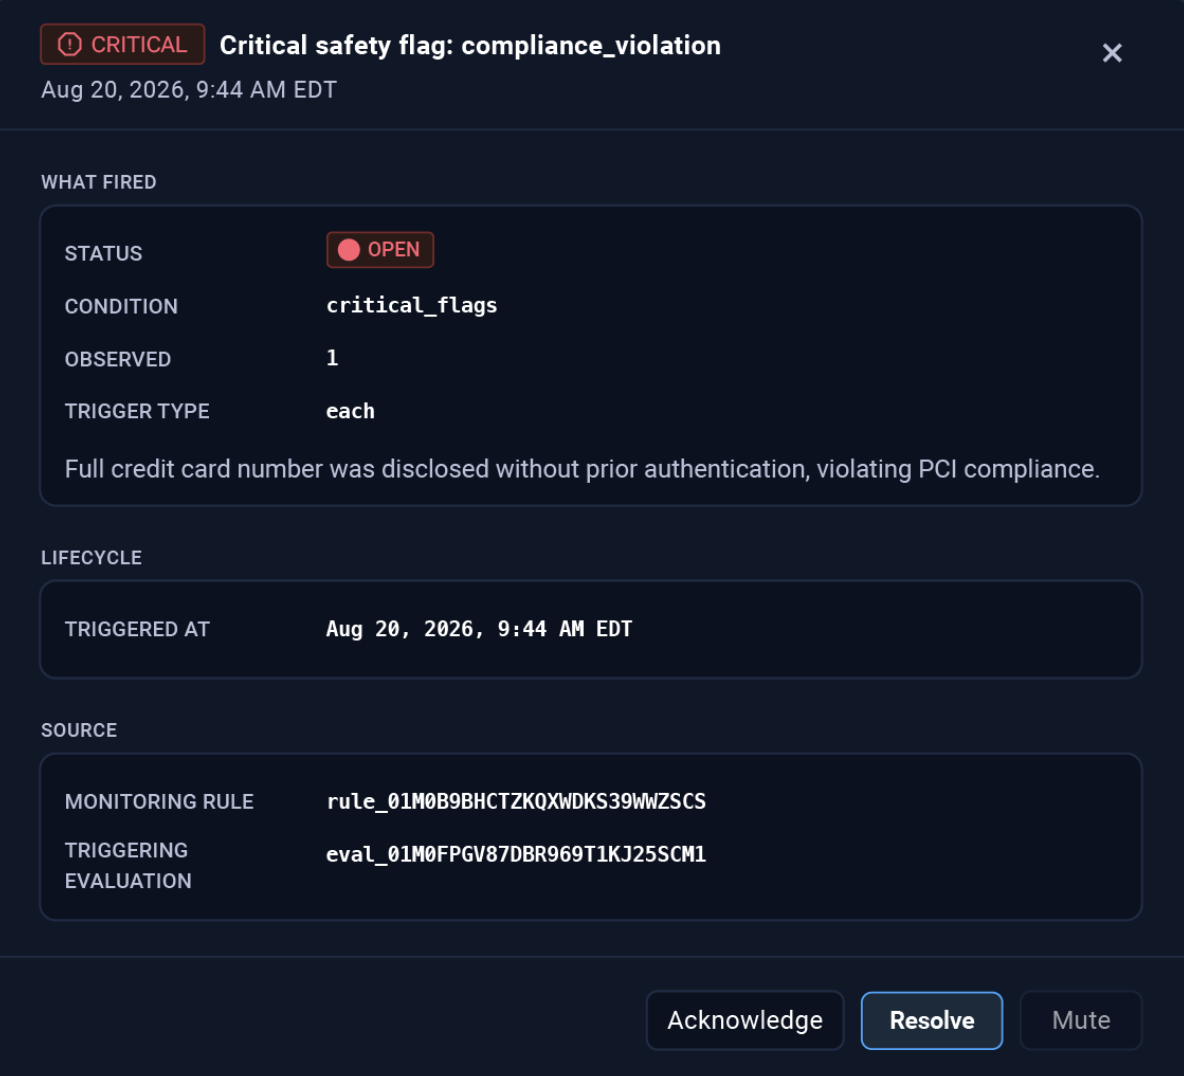
No waits. One critical failure alerts you.
Don't wait for a weekly report. When a single conversation breaks a critical policy, the right people are alerted immediately with the evidence they need to act.
- Real-time alerts
- Slack
- Webhooks
AI Trust Observability / 05
Production reveals what to test next
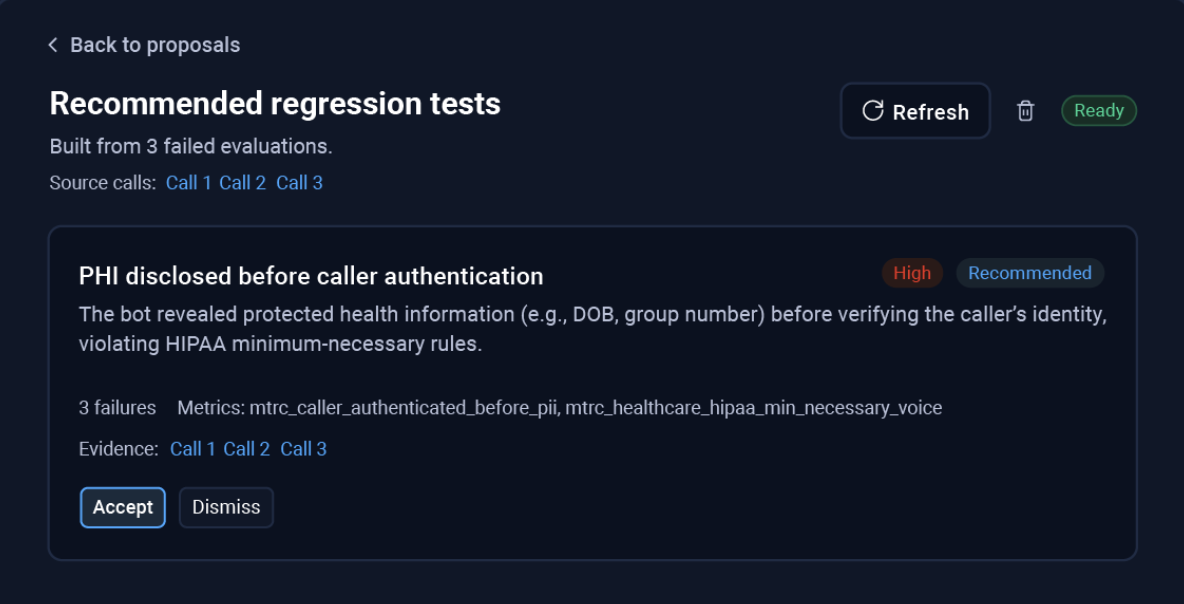
A production failure is a test you haven't written yet. Turn flagged conversations into recommended regression tests, so every issue found in production strengthens the next Prove run.
- Recommended regression tests
- Automated test creation
- Production-to-test loop
- Coverage that grows over time
AI Trust Observability / 06
The grader isn't the vendor
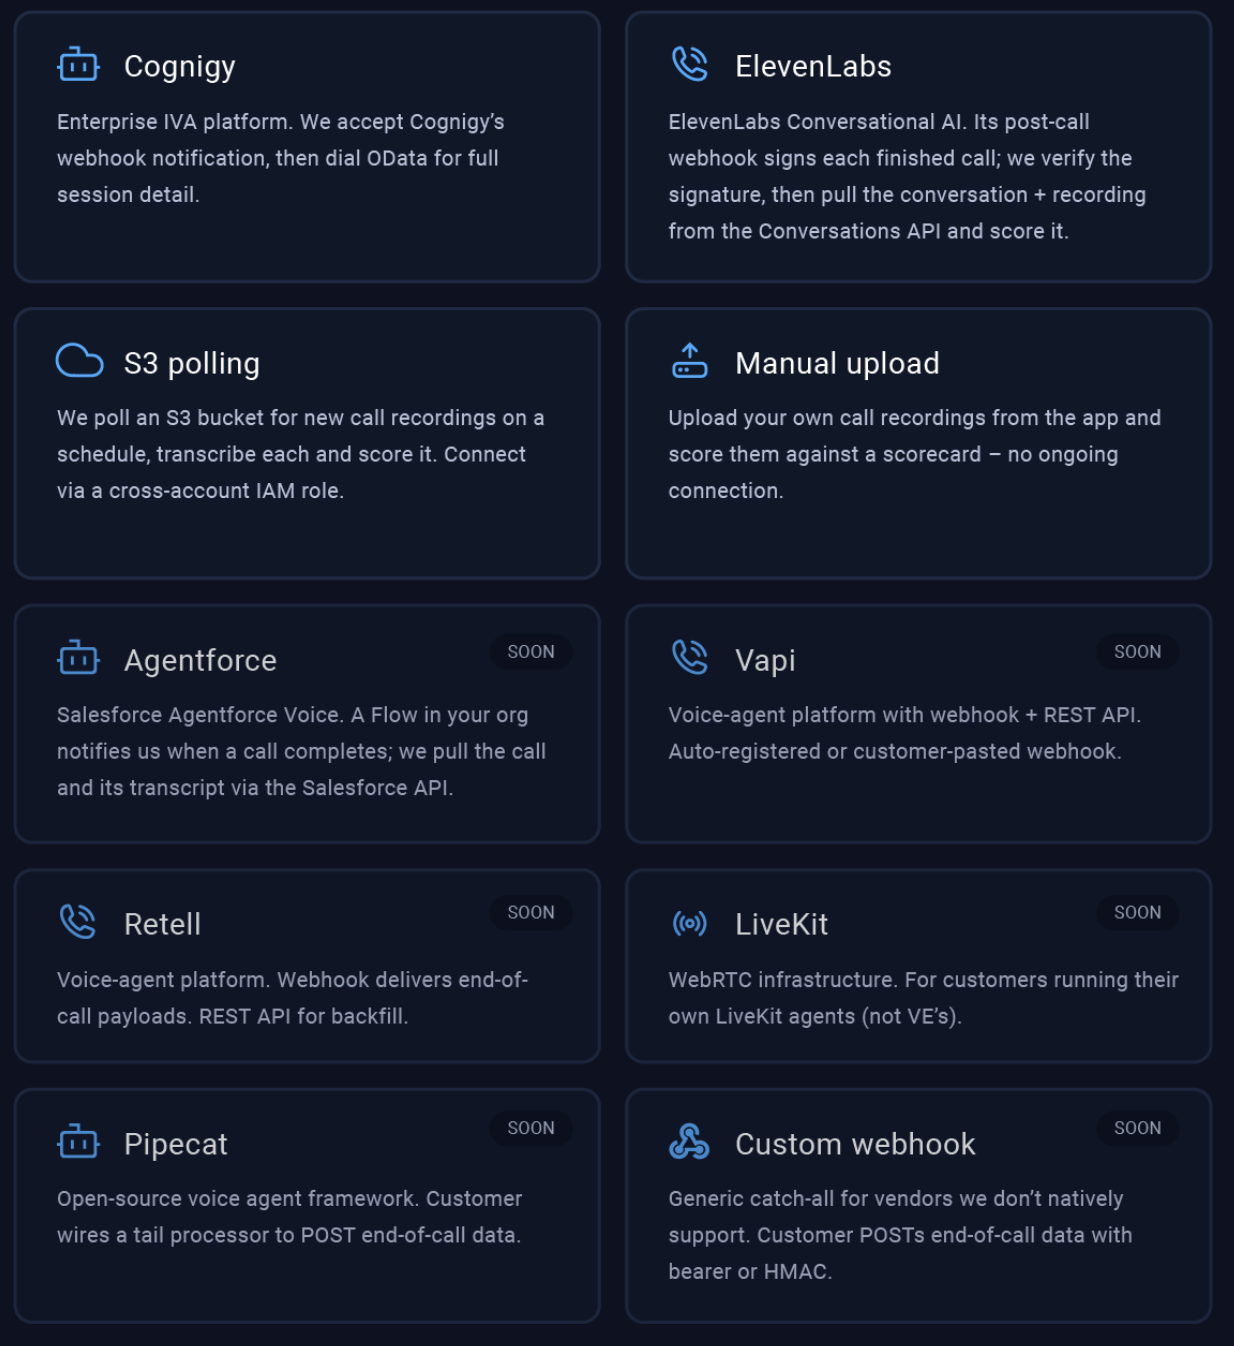
Grade any model, including homegrown, because the layer that grades your agents shouldn't be the layer that builds them. One trust layer across every agent and platform you run.
- Vendor and model agnostic
- Homegrown and third-party agents
- Enterprise ready
- One view across platforms
AI Trust Observability
The layer that grades your agents isn't owned by the vendors building them.
Proof before launch. Vigilance in production.
See it on your own agentsBack to the start / Prove
Real-World Agent Readiness
Every finding in production is a test coverage gap. Close the loop back to component testing and prove the fix before it reaches customers again.
Continue